
An Intuitive Look at Tomasulo, RV32IM Out-of-Order Implementation and Optimisation


This post is a continuation of the RISC-V pipeline optimisation post. That post took rv32i-pipe from a CPI of 1.3158 to 1.0675 and the dual issue rv32i-superscalar to 0.7271. This post asks what comes next: what out of order execution actually is, how Tomasulo’s scheme works block by block, and what happened when it was built and measured on the same RV32IM cores with the same benchmark. Every number here comes from simulation runs on my own implementations, and every CoreMark figure is from Verilator.
Special thanks to BitLemon for Out-of-Order Execution (Tomasulo’s Algorithm), and to Core Dumped. Both channels did a lot of the heavy lifting getting computer architecture intuition into my head.
This project was ambitious relative to what I knew going in. Most of the learning came from open source repos and videos available online, including Onur Mutlu’s advanced computer architecture classes. I did not absorb all of that before trying anyway. Rather than restarting from scratch I continued from the previous post’s cores, and worked on speedup alongside correctness from the start. Without correctness the numbers mean nothing, fast or slow.
I initially prototyped Tomasulo in C++, which helped me understand the machinery well enough to get an out of order core working and passing the ISA tests. The results were not particularly different from the in order versions, but the prototype gave me something working to translate into RTL. I also started the RTL rewrite with future variants in mind, since scaling the design to superscalar or more optimised versions can sometimes require taking a completely different design approach rather than simply adding another feature.
Scope of the measurements
The OoO measurements use the included fixed-latency memory model, keeping the reorder and scheduling machinery visible.
The dual issue core is also still small, so the extra width does not provide enough independent work on this workload to repay the overhead of OoO. These results are therefore not a claim that OoO is ineffective. They show what happens when it is added to a small, already optimised core.
Connecting it back
Before getting into the details, the same disclaimer as the previous post applies. Modern high performance cores from ARM, Intel, or Apple are wide out of order superscalar machines with large instruction windows, sophisticated predictors, and execution resources far beyond anything described here. All CoreMark/MHz figures are frequency normalised, and there is no synthesis in this post, so timing closure and Fmax are out of scope. The goal is to show how the mechanism works and what it measured on small cores, not to match commercial designs. Synthesis and implementation efforts using Yosys with the Sky130 standard cell library, OpenLane based hardening, and FPGA flows are part of the larger project and are treated separately. If you are interested in those areas, refer to the full project page linked below.
Out of order execution has been on my project list for a long time. It is the most ambitious build in this series by a good margin. I am still learning as I go, and I will update this post if and when that is required.
Quick Note
I felt a bit lazy, so I used a few images directly that were generated with the help of OpenAI’s image_gen, paired with GPT-5.6 Luna. I also used Kimi 2.6 for text formatting (this is my first time using it for writing, so the tone and style might feel a bit different) to maintain a smooth flow in the writing and avoid any mistakes along the way. Credits wherever needed.
Naming Convention
A naming note before anything else, since the variant names get long. The previous post built several in order features and stacked them onto a core name: early branch resolution, a hybrid predictor, a branch target buffer, a return address stack, hazard cleanup, load-use optimisation, and full load-use forwarding. Every core in this post that carries all of those is written with the suffix -FE (front end) instead of spelling out -br-hybp-btb-ras-hzopt-luopt-fulu every time. So rv32i-pipe-FE is rv32i-pipe with that full front end treatment, and rv32i-super-FE is the dual issue version with the same treatment. Where a core needs two of the out of order fixes described later, an extra o marks it: rv32i-ooo is single issue out of order, rv32i-oooo has the two fixes on top. The tables use short names to keep the rows readable: pipe, pipe opt, super, super opt, plus pipe ooo, pipe opt ooo, super ooo, super opt ooo and super opt oooo.
Out of order intuition: three small examples
Start with what the machine is actually for, before any results. An in order core issues instructions in the exact order the program lists them. If instruction 2 is waiting on something, instruction 3 waits too, even if instruction 3 has nothing to do with instruction 2. Out of order execution lets the hardware pick a different instruction to run while the stalled one waits, then puts the results back in the original order when it is time to update memory and registers. The program behaves exactly as written. Only the order work gets done inside the machine changes.
To see why this needs care, start from the two operations any instruction can do to a register: read it or write it. Two instructions touching the same register name gives four possible combinations, not three:
- read then read (RAR)
- read then write (RAW)
- write then read (WAR)
- write then write (WAW)
RAR never causes a problem. Reading a register twice does not change what is stored there, so it does not matter how many instructions read it or in what order they read it. The value sits still. This is also why a register file is usually built with two read ports and one write port, 2R1W: multiple reads in the same cycle are free of conflict by construction, so hardware gives out as many read ports as the pipeline needs, backed by a single SRAM array and a couple of read muxes at the output picking which row to return on each port. Only a write changes the value, so only combinations involving a write are worth naming:

- RAW (read after write). Instruction 2 reads a value that instruction 1 writes. This is a true dependency. Instruction 2 cannot run correctly before instruction 1 produces the value.
I1   R3 = R1 + R2
I2   R5 = R3 + R4
I1 produces R3. I2 needs R3 to compute R5. In a five stage pipeline I2 reaches the stage that reads R3 before I1 has written it back, so the value I2 sees is stale unless something intervenes: a stall, or forwarding the result straight from where I1 computed it. The rule for spotting it: I1 writes R3, I2 reads R3, and that overlap is the hazard. I1’s range (what it writes) intersects I2’s domain (what it reads).

- WAR (write after read). Instruction 2 writes to a register that instruction 1 still needs to read. If instruction 2 runs first, instruction 1 reads the wrong value. This is not about data flow, it is about two instructions racing to touch the same name.
I1   R1 = R2 x R3
I2   R2 = R4 + R5
I1 reads R2 to compute R1. I2 writes a new value into R2. In an ordinary five stage pipeline this never actually breaks anything, because I1 reads its operands early in the pipe and I2 cannot write back before I1 has already moved past its read stage: reads always land before the later write reaches the register file. The hazard only becomes a real risk once instructions are allowed to complete out of the order they were fetched in, for example if I2 runs ahead because I1 is delayed waiting on something else, or under auto increment and auto decrement addressing where a register is written before the next instruction has even been fetched. The rule for spotting it: I1 reads R2, I2 writes R2, so I1’s domain intersects I2’s range.

- WAW (write after write). Instruction 1 and instruction 2 both write the same register. If they run out of order, whichever one finishes last decides what the register holds, which may not match program order.
I1   R3 = R1 * R2
I2   R3 = R4 + R5
Both instructions write R3. In program order I2’s write should be the one that survives, since it comes second. In an ordinary five stage pipeline this also cannot go wrong, because writeback happens in the same order instructions were fetched. It becomes a hazard only when the two writes can complete out of that order, for instance if I1’s multiply takes longer than I2’s add and I2 finishes first: whichever write actually lands last in time wins, and if that is I1, the register ends up holding the wrong value for anything read after it. The rule for spotting it: I1 writes R3, I2 writes R3, so I1’s range intersects I2’s range.

RAW is real. The value has to exist before it can be read, in any machine, in any order. WAR and WAW are not about values at all. They exist only because both instructions happen to use the same register name. An out of order machine cannot let WAR or WAW hazards decide execution order, because ordering only for the sake of a shared name throws away exactly the freedom the machine exists to use. The fix, covered in full further down, is renaming: give every write a fresh, unique storage slot instead of reusing the 32 architectural register names, so two writes to “x1” become two writes to two different slots and the false ordering disappears. What remains after renaming is only RAW, and RAW is what the machine actually has to respect.
Example 1: hiding a slow producer. A load misses and takes 100 cycles. The next instruction needs the loaded value. The one after that does not.
lw   x1, 0(x2)      # slow, 100 cycles
add  x3, x1, x4     # true RAW on x1, must wait
add  x5, x6, x7     # independent of both
in order:   lw waits 100 -> add x3 waits 100 -> add x5 waits 100, then runs
out of order: add x5 runs in cycle 1 while lw is still in flight
              add x3 runs when x1 arrives, retire stays in program order
The in order core stalls everything behind the load. The out of order core runs the independent add at once and retires all three in program order. Nothing about the program changed. Only the execution order changed.

The picture above uses a factory as the analogy: a CPU is RAM feeding a control unit and ALU, the same way a warehouse feeds a shop floor with a buffer, an operator, and a machine. In order execution processes job I1 fully (fetch, decode, execute, writeback) before I2 can leave its stall and move on, even though I2 was ready to decode two cycles earlier. Out of order execution lets I2, I3, and I4 slide left into the cycles I1 leaves idle, so the same four jobs finish sooner without changing what each job does or the order results land in.
Example 2: interleaved independent chains. Compilers interleave independent work to fill load delay slots, but they can only see a few instructions ahead and must respect register pressure. A windowed core sees further:
lw   x1, 0(x10)
lw   x2, 0(x11)     # independent of line 1, runs in parallel
add  x3, x1, x5     # waits on line 1 only
add  x4, x2, x6     # waits on line 2 only
An in order dual issue core pairs lines 1 and 2, then stalls the pair of lines 3 and 4 until both loads complete. An out of order core runs each add as soon as its own load completes. When the two loads have different latencies, the difference shows up directly as saved cycles.
Example 3: false dependencies. These three instructions have no true link between lines 1 and 2. They only reuse the name x1.
add  x1, x2, x3     # writes x1
add  x1, x4, x5     # WAW on x1, no true link to line 1
add  x6, x1, x7     # reads only the second x1
An in order core with a single register file must run line 2 after line 1 completes, because both write the same physical register and line 2 would clobber a value line 3 might need. That ordering constraint is artificial. It comes from having 32 register names for an unbounded number of live values. Renaming removes it:
line  arch rd  physical tag  map state after rename
1     x1       p7            x1 -> p7
2     x1       p8            x1 -> p8 (line 1 keeps p7, both run free)
3     x1       p8            reads p8, the latest x1

After renaming, lines 1 and 2 write different physical registers and can execute in any order or in parallel. Only the true RAW from line 2 to line 3 remains, expressed as p8. This is the core idea of Tomasulo’s scheme: keep program order in the rename map and the retire logic, and let execution order follow data readiness instead.
A cycle by cycle picture. Take four instructions where the first is a slow 3 cycle multiply and the second needs its result:
mul  x1, x2, x3    # slow, 3 cycles
add  x4, x1, x5    # RAW on x1, must wait
add  x6, x7, x8    # independent
add  x9, x10, x11  # independent
Assume all four are already dispatched, single issue, one execution per cycle:
cycle  in order runs  OOO runs
1      mul            mul
2      stall          add x6
3      stall          add x9
4      add x4         add x4
5      add x6         -
6      add x9         -
The in order core burns cycles 2 and 3 doing nothing. The out of order core fills them with the two independent adds and finishes in 4 cycles instead of 6. The saving is exactly the independent work available during the stall, capped by issue width: two ready instructions at one per cycle, two cycles saved. Nothing about the program changed, and retire still happens in program order at the end. Sliding ready work into stall cycles is the entire game. Everything else in this post is machinery to enable it and measurement of what that machinery costs.
Why retire must stay in order. Execution can run free, but the visible state cannot. An interrupt landing mid stream needs a precise point: everything before some instruction done, nothing after it started. A store that becomes visible and later turns out to be on a mispredicted path cannot be undone. So the machine needs a structure that remembers the original program order, holds finished results aside, and commits them strictly in order. That structure is the reorder buffer, and it is the reason out of order execution is safe to build at all.
The window: how far ahead the machine can see. The machine can only reorder instructions it has fetched but not yet retired. That live set is the window, and its size caps everything: independent work beyond the window might as well not exist, because the machine cannot see it yet. When the window fills up, dispatch stops and the machine stalls in order at the front, no matter how much parallelism waits further down the program. That stall is backpressure, the one in order stall no amount of reordering removes. You cannot execute what you have not fetched.
What a mispredict costs. Every instruction younger than a mispredicted branch is garbage the moment the branch resolves. The machine throws all of it away and restarts fetch on the right path. A deeper window holds more speculative work, so each flush discards more. Prediction accuracy therefore matters more in an out of order core, not less: the window multiplies the benefit of correct guesses and the cost of wrong ones.
The machinery that makes this work has six pieces, laid out roughly in the order an instruction meets them:
┌───────┐   ┌─────────┐   ┌─────────────┐   ┌───────┐
│ fetch │   │rename / │   │  ALU queue  │   │ ALU0  │
│   +   │──>│dispatch │──>│  MD queue   │──>│ ALU1  │
│predict│   │ROB alloc│   │  BR queue   │   │  MD   │
└───────┘   └─────────┘   │  LS queue   │   │  BRU  │
                          │ oldest 1st  │   │  LSU  │
                          └─────────────┘   └───────┘
                                 │              │
                               ┌─┬──────────────┬┐   ┌─────────┐
                               │       CDB       │──>│   ROB   │
                               │  wakeup by tag  │   │ retire  │
                               └─────────────────┘   └─────────┘
Instructions fetch and get renamed in order, sit in per-class queues until their inputs are ready, execute whenever a unit is free, broadcast results on a shared bus that wakes up anything waiting on that value, and retire in order at the end. That sketch is a summary of a conclusion. The section below derives every block in it from the problem that forces it to exist, with the Verilog for each piece.
Tomasulo from zero
Tomasulo published the scheme in 1967 for the IBM 360/91 floating point unit. It generalises the older scoreboard idea by adding renaming, and every later out of order machine, from the MIPS R10000 to whatever runs in a current phone, is some variation on the same six ideas below. None of the blocks are arbitrary. Each one is the smallest structure that closes a specific hole, and the hole shows up the moment you try to build the freedom the examples above promised.
The goal is to run instructions in whatever order finishes fastest, while the program still observes strict program order from the outside. Speed wants total freedom, correctness wants total order, and every block below exists because one half of that tension demands it. Start from the freedom side and follow the failures as they show up.
Rename map. WAR and WAW orderings exist only because 32 register names get reused by an unbounded stream of writes. As long as two writes share the name x1, the machine has to pretend they are ordered, and that pretence kills exactly the freedom the whole exercise is trying to buy. Example 3 showed this directly: two unrelated adds, both writing x1, forced to serialise for no reason except the name. There are only two ways to make a false dependency stop mattering: detect that it is false and ignore it, or remove the collision that created it. Detecting falseness per pair, per cycle, against every other in flight instruction is the same combinational blowup the previous post ran into with forwarding logic for wide issue, and it gets worse here because the window is much deeper than two slots. Removing the collision instead means giving every write somewhere new to land, which is cheaper and scales with window size instead of window size squared. So names stop getting reused at execution time. Every dispatched write gets a fresh tag, a table remembers which tag each architectural register currently maps to, and sources point at tags instead of names, or read the value directly if the producer has already finished. That table is the rename map. The fresh tag allocator plus a ROB entry for every dispatched instruction is dispatch. In this build the ROB index itself serves as the tag, so no separate physical register file or free list is needed, the ROB slot is the physical register:
// Rename sketch (simplified): architectural rs to physical tag,
// plus a ready flag that says whether the value is already in the ROB.
wire [4:0] tag_a = rename_map[id_rs1];
wire [4:0] tag_b = rename_map[id_rs2];
wire       rdy_a = rob_ready[tag_a];
wire       rdy_b = rob_ready[tag_b];
// rd gets a fresh tag at dispatch; WAW and WAR vanish by construction.
Reorder buffer. Once renaming lets results finish early, out of order, and sometimes speculatively, the visible state of the machine is no longer the state of any single instruction boundary. An interrupt arriving mid stream needs a clean line: everything before it done, nothing after it started. A store that becomes visible and later turns out to sit on a mispredicted path cannot be pulled back once memory has seen it. Letting results commit to architectural state the moment they finish, and unwinding if something later turns out wrong, works for registers but not for stores, since a memory write is irreversible the instant something else reads it. The safer route is to never let a result touch architectural state until the machine is certain it belongs there: hold every finished result somewhere temporary and release it only when everything older has already been released. That ledger, remembering original program order and committing strictly in that order, is the reorder buffer. The commit pointer walking its head is retire. Stores write memory at retire, never earlier. Precise exceptions fall out of this for free, since architectural state always reflects a clean prefix of the program. If the ROB or the target queue is full, dispatch stops, and that stall is backpressure, the only in order stall left anywhere in the machine.
Issue queues. An instruction whose operands are not ready has to sit somewhere without blocking the instructions behind it. A FIFO cannot do this: the waiter at the front stalls everyone behind it even if they are ready to run right now, which is exactly the in order stall this whole scheme exists to remove. The alternative is unordered waiting: give every stalled instruction its own slot, independent of every other slot, and let each slot announce readiness on its own schedule instead of in arrival order. Picking among several ready waiters at once then needs its own logic, since arrival order no longer tells you who goes first, and the cheap fallback is oldest wins, since the instruction that has waited longest is usually the one blocking the most work behind it. Each waiter gets an entry holding its op, its tags, and whatever values it has already captured, and entries become runnable the moment all their tags arrive. The entry pool is the issue queue, also called reservation stations. Position in it carries no scheduling meaning, which is what actually decouples program order from execution order: a young instruction can sit in slot 0 and an old one in slot 15 with no penalty either way. Picking among runnable entries goes oldest first, so the oldest waiter cannot be starved by younger ones:
// Oldest first select (simplified): key 0 is the head, min key wins.
integer i;
always_comb begin
  pick = 4'hF; best = 4'hF;
  for (i = 0; i < 16; i = i + 1) begin
    if (iq_valid[i] && iq_ready[i] && (iq_key[i] < best)) begin
      best = iq_key[i];
      pick = i[3:0];
    end
  end
end
Split execution units. Suppose all waiting instructions sat in one shared queue feeding one shared ALU, one multiplier, and one divider. A divide occupies the divider for 12 cycles, which is fine for the divide itself, but every instruction behind it in a single ordered queue, including ALU ops whose unit is sitting idle, has to wait its turn to even be looked at. Same disease as the FIFO above, just moved one stage later. The issue queue already solved unordered waiting within one pool, and the same idea has to apply across pools too, or one slow class holds the fast ones hostage no matter how good the per entry selection logic is. Splitting one queue into several, one per functional class, means a stalled divide only occupies the queue that feeds the divider: ALU queue, MD queue, branch queue, load store queue, each draining on its own schedule with its own wakeup and select, sized to its own latency. A 12 cycle divide stalls only the MD queue while ALU ops and branch resolution keep flowing untouched. Dispatch has to steer every instruction to the correct queue and each queue needs its own select logic, but the alternative is letting the slowest unit in the machine set the pace for every instruction that never goes near it.
Common data bus. With a window full of waiters split across several queues, point to point forwarding from each producer directly to each consumer stops scaling almost immediately: every new waiter needs a wire back to every instruction that might produce its operand, and that wiring grows with the square of the window size. The usual fix for a fan out problem like this is to stop routing point to point and broadcast instead: put the result on a shared line and let every listener check the tag on its own, with the only requirement being a tag on the broadcast so a listener can tell whether the value going past is the one it wants. Each finishing unit broadcasts its tag and value on a shared bus, and every queue entry plus the ROB entry holding that tag captures it the moment it appears, all in the same cycle. That broadcast is the common data bus. One send wakes every waiter on that tag at once, with no per pair wiring. With two completions possible per cycle, two buses are needed, plus arbitration for the rare case where more than two units finish at once.
Fetch, prediction, and the flush path. None of the above says anything about how instructions arrive in the first place. Fetch has to keep delivering a stream fast enough to keep the queues fed, and it has to guess which way every branch goes before that branch is anywhere close to resolved, or the window starves at the very first branch it meets. Guessing means sometimes guessing wrong, and everything fetched on a wrong guess is invalid the instant the branch resolves. Once wrong guesses are unavoidable, the machine needs a predictor good enough that they are rare, and a way to undo one cheaply when it happens, reaching every structure a wrong path instruction could have touched, the rename map most of all, since a wrong path write could otherwise leave a live tag pointing at a value that will never arrive. When a prediction is wrong, everything younger than the branch is garbage: the machine kills those entries by positional tag, restores the rename map to the state it held at the branch, and restarts fetch on the correct path. Branches confirm or trigger the flush at retire or at resolve depending on the design. The deeper the window, the more speculative work a single wrong guess discards, which is why prediction quality matters more, not less, as the window grows.
Walk Example 3 through all six pieces to see them act together. Lines 1 and 2 dispatch in order and rename x1 to p7 then p8. Both issue to the ALU queue and sit in reservation stations until their operands are ready. They execute in whatever order the ALU is actually free, possibly line 2 first. Each broadcasts its result on the CDB with its own tag. Line 3 waits on p8 alone and runs the moment p8 arrives, regardless of what else is happening. Retire writes p7, then p8, then line 3, strictly in program order, with fetch and prediction having supplied the whole stream up front. The register file ends exactly as sequential execution would have left it. The intermediate order left no trace anywhere an architectural observer could see it.
Six blocks, in the order an instruction actually meets them: fetch with its flush path, the rename map, the issue queues, the split execution units, the common data bus, and the reorder buffer. That is the same six box sketch from the intuition section above, just arrived at by asking what breaks without each piece instead of declaring the pieces up front.
So what should OoO actually buy us?
At this point the intuition sounds straightforward. If an instruction is waiting, the machine should stop waiting for it and find something else to do. Register renaming removes false dependencies, the issue queues let ready instructions move around stalled ones, and the ROB lets all of that happen without changing the architectural order.
So the obvious question is not whether out of order execution works in principle. It is:
After already building a well optimised dual issue core, how much performance is actually left for OoO to find?
The previous post already removed many of the stalls that an in order core can cheaply avoid. rv32i-super-FE has two issue slots, strong branch prediction, early branch resolution, BTB and RAS support, hazard cleanup, and full load-use forwarding. It reaches a CPI of 0.7271 on CoreMark, or 1.3752 IPC. The remaining headroom is therefore much smaller than it was for the original five stage pipeline.
That makes OoO an interesting test rather than an automatic upgrade.
Where OoO should become useful
The mechanism should become more valuable when there is something substantial to hide:
- Long memory latency. A slow load can leave dependent instructions waiting while independent work further down the window remains executable.
- Multiple branches in flight. A larger speculative window should allow useful work beyond one unresolved branch instead of stopping dispatch at every branch.
- An out of order load/store queue. Memory operations should be able to execute when their addresses and dependencies are ready rather than waiting for in-order retirement.
- More memory bandwidth. A second load port gives the window somewhere to send independent loads instead of turning memory into the bottleneck.
- Wider issue. More execution width gives OoO more opportunities to exploit independent instructions, provided the workload actually contains them.
Those are the conditions under which the basic intuition should translate into a measurable advantage.
But there is a catch.
OoO does not get the reordering for free. Every instruction now pays for rename, ROB allocation, queue insertion, wakeup, selection and retirement. The question is whether the stalls it removes are large enough to repay that machinery.
So rather than assuming that OoO must be faster, I built it in stages and measured each one against the same cores and the same CoreMark workload.
The first experiment is deliberately the simplest: put OoO on the original single issue pipeline.
If the machinery itself is useful, it should at least reduce stalls there.
If it is not, the numbers should tell us exactly what the overhead costs.
Jump to final 9 config numbers
TL;DR / Results
The short version is that OoO does not automatically beat a well tuned in order core. The experiments show where the mechanism helps, where its overhead dominates, and what has to change before the balance flips.
- Single issue OoO on the plain pipe:
rv32i-ooois 17.4% slower thanrv32i-pipeat O3 i100. With only a 1 IPC ceiling, the extra machinery has no throughput headroom to pay for itself. - Single issue OoO with the optimised frontend:
rv32i-ooo-FEstill loses. Better prediction removes most of the branch penalty, but the rename, ROB, queue and retirement machinery still costs more than the remaining stalls it hides. - Dual issue OoO: starting from
rv32i-super-FE, the first correct implementation is much slower. Two measured fixes, routing MUL to the ALU pipes and resolving branches in the same cycle, recover 18.9% of its cycles. - Final result:
rv32i-super-oooo-FEreaches 3.5854 CoreMark/MHz at i100 O3. That is 13.1% ahead of the optimised single issuerv32i-pipe-FE, but behind the tuned dual issuerv32i-super-FEat 4.6545. - Why: the counters point mainly to one branch in flight, an in order single port load path, and the remaining JALR gates.
Both sets of measurements point at the same change. Latency tolerance here needs speculative load addresses, several misses in flight, and more than one branch in flight. Those are memory pipeline changes rather than predictor changes, and the two OoO fixes already show what that kind of fix is worth: together they beat the entire front end.
Jump to final 9 config numbers
The four in order designs in brief
These are the four non OOO variants from the previous post. They are the baselines every out of order result here is compared against, so their numbers are repeated below as a table, with the raw terminal block after it. All figures are O3, 100 iterations, rv32im, Verilator.
| Variant | Cycles | CPI | CoreMark/MHz | IPC |
|---|---|---|---|---|
rv32i-pipe | 38877313 | 1.3158 | 2.5722 | 0.7600 |
rv32i-pipe-FE | 31540922 | 1.0675 | 3.1705 | 0.9368 |
rv32i-superscalar | 30832113 | 1.0435 | 3.2434 | 0.9583 |
rv32i-super-FE | 21484390 | 0.7271 | 4.6545 | 1.3752 |
design               cycles     CPI      CoreMark/MHz   IPC
rv32i-pipe           38877313   1.3158   2.5722         0.7600
rv32i-pipe-FE        31540922   1.0675   3.1705         0.9368
rv32i-superscalar    30832113   1.0435   3.2434         0.9583
rv32i-super-FE       21484390   0.7271   4.6545         1.3752
rv32i-pipe. Plain five stage pipeline with forwarding and stall on load use. No prediction. Branch resolves at the end of EX. CPI 1.3158.
rv32i-pipe-FE. rv32i-pipe with the full treatment. Early branch resolution in ID gave the largest single gain, then the 2 bit predictor, the BTB, generalised load forwarding, the tournament predictor, and the JAL fast path with RAS. Total gain over baseline: +23.26%.
| Step | CoreMark/MHz gain |
|---|---|
| Early branch resolution | +8.557% |
| 2-bit direction predictor | +6.547% |
| BTB | +3.458% |
| False hazard cleanup | +0.002% |
| Store data forwarding | +0.013% |
| Generalised load forwarding | +1.996% |
| Tournament predictor | +0.455% |
| JAL fast path + RAS | +0.080% |
| Final (1.0675 CPI, 3.1705 CoreMark/MHz) | +23.26% total |
rv32i-pipe-FE waterfall (CoreMark/MHz gain per step):
early branch resolution      +8.557%
2-bit direction predictor    +6.547%
BTB                          +3.458%
false hazard cleanup         +0.002%
store data forwarding        +0.013%
generalised load forwarding  +1.996%
tournament predictor         +0.455%
JAL fast path + RAS          +0.080%
final: 1.0675 CPI, 3.1705 CoreMark/MHz
rv32i-superscalar. Dual issue, in order, unoptimised. CPI 1.0435, only 2.3% ahead of rv32i-pipe-FE, because it spent its extra width on the same avoidable stalls.
rv32i-super-FE. The rv32i-superscalar core with the same ideas applied in dual issue form. Load use forwarding was the dominant win at +17.026%, because a load RAW hazard that squashes slot 1 wastes two issue opportunities per stall cycle instead of one. Total: 1.435x over its own baseline, 46.8% ahead of rv32i-pipe-FE.
| Step | CoreMark/MHz gain |
|---|---|
| Early branch resolution | +7.871% |
| Hybrid predictor | +6.489% |
| BR + HyBP combined | +1.350% |
| BTB + RAS | +1.474% |
| Hazard optimisation | +3.804% |
| luopt + fulu | +17.026% |
| Final (0.7271 CPI, 4.6545 CoreMark/MHz) | 1.435x total |
rv32i-super-FE waterfall (CoreMark/MHz gain per step):
early branch resolution      +7.871%
hybrid predictor             +6.489%
BR + HyBP combined           +1.350%
BTB + RAS                    +1.474%
hazard optimisation          +3.804%
luopt + fulu                 +17.026%
final: 0.7271 CPI, 4.6545 CoreMark/MHz
A counter instrumented rv32i-super-FE run showed where its remaining cycles go: slot 1 bubbles 19.1% of cycles, slot 1 squash 22.2%, of which 73.6% is control driven and 26.3% is load RAW driven. Control flow dominates the leftover loss. That breakdown matters later, because rv32i-super-oooo-FE attacks exactly this loss and the numbers say how much of it was actually recoverable.
Why wider in order gets hard
A dual issue in order core can retire two instructions per cycle only when the pair is independent. This pair cannot dual issue:
add  x1, x2, x3     # writes x1
add  x4, x1, x5     # reads x1, must wait
This pair can:
add  x1, x2, x3     # writes x1
add  x4, x6, x7     # touches nothing the first writes
Checking that condition in hardware means comparing every destination of every earlier in flight instruction against every source of every candidate instruction, every cycle. For dual issue the checks split into two groups: intra cycle (slot 0 destination vs slot 1 sources) and cross cycle (both slots vs the previous cycles results still in flight). The previous post counted roughly 8 forwarding cases for dual issue and about 44 for four wide before simplification. The count grows faster than the width because every new slot adds checks against every other slot and against every in flight producer.
Branches make it worse. If slot 0 holds a branch, slot 1 cannot safely execute until the branch outcome is known, so the second slot is restricted or squashed. Loads make it worse in the other direction: a load in either slot whose result the next pair needs forces the next pair to stall or squash. The in order core has exactly one tool for all of this: stop issuing. Every dependency, whether true or false, serialises the machine at the issue point. Out of order execution exists to stop paying that price for dependencies that are not real.
Worth pausing on that last sentence, because it is easy to read out of order execution as a superscalar feature. It is not. The dependency problem above shows up the moment a core has to decide what runs next, regardless of issue width. Out of order execution is a scheduling policy, and the design lineage below is where it fits into the broader picture, single issue included.
single cycle -> multicycle -> 5 stage pipe -> dual issue super -> OOO super
1 IPC max       1 IPC max     1 IPC max       2 IPC max           2 IPC max
slow clock      fast clock    overlapped      needs               finds
1 per cycle     1 at a time   1 per cycle     independent pairs   independent pairs
Single cycle is simple and slow. Multicycle improves the clock but keeps a CPI of 3 to 5 with one instruction in flight at a time. Pipelining overlaps the stages and raises steady state throughput toward 1 IPC. Deepening the pipeline past that point, superpipelining, shortens the clock but widens the misprediction penalty and stretches every producer to consumer distance, which is why the previous post stopped at 5 stages and removed overhead instead: early branch resolution, prediction, BTB, RAS, and generalised forwarding. Superscalar widened issue instead of deepening the pipe: two instructions per cycle when they are independent.
Out of order execution sits on top of any of these, not just the wide one. A single issue core still has an IPC ceiling of 1, but it can still stall on a dependency it did not need to respect, the same RAW, WAR, WAW picture from the examples above, just with one instruction moving instead of two. That is why this post builds and measures an out of order version of the plain single issue pipe first, before touching the dual issue core. If the mechanism only mattered at superscalar widths, that first build would be pointless. It is not: it isolates the cost of the machinery itself, separate from whatever the extra issue width does.
For the dual issue core specifically, with a realistic integer dependency rate $d$, the effective CPI floor is:
$$\text{CPI}_{\text{floor, dual}} = 0.5 + 0.5d$$At $d = 0.3$ the floor is about 0.65. The optimised rv32i-super-FE measured 0.7271, which is why the headroom left for any further technique on that core was always small. That number frames the dual issue results later in this post, but the single issue results that come first are answering a different question: what out of order execution costs on its own, with no extra width to pay for it. The dual issue experiment then asks the more interesting question: once the core already has two places to execute, can OoO use those places more effectively than an in order scheduler can?
OoO on the plain pipe: rv32i-ooo
The first experiment put a scalar Tomasulo core on the unoptimised rv32i-pipe base (rv32i-ooo): rename map, ROB, issue queue, single issue and single retire, predict not taken frontend. Same binaries, same Verilator flow, same retired instruction counts (any deviation would mean wrong path retirement; all runs matched). Result:
| Config | rv32i-pipe cycles | rv32i-pipe CM | rv32i-ooo cycles | rv32i-ooo CM | Cycles ratio | CM ratio |
|---|---|---|---|---|---|---|
| i1 | 402765 | 2.4828 | 472204 | 2.1177 | 1.172x | 0.853x |
| i10 | 3900320 | 2.5639 | 4578130 | 2.1843 | 1.174x | 0.852x |
| i100 | 38877313 | 2.5722 | 45639092 | 2.1911 | 1.1739x | 0.852x |
| O2 i100 | 41275362 | 2.4228 | 48936322 | 2.0435 | 1.186x | 0.843x |
O3, Verilator. CM = CoreMark/MHz:

          rv32i-pipe          rv32i-ooo           cycles ratio   CM ratio
i1        402765 / 2.4828     472204 / 2.1177     1.172x         0.853x
i10       3900320 / 2.5639    4578130 / 2.1843    1.174x         0.852x
i100      38877313 / 2.5722   45639092 / 2.1911   1.1739x        0.852x
O2 i100   41275362 / 2.4228   48936322 / 2.0435   1.186x         0.843x
rv32i-ooo is slower everywhere: 17.4% more cycles at i100 O3. The cause is structural, not a bug. Both cores have a peak IPC of 1.0, so rv32i-ooo cannot retire faster than rv32i-pipe under any circumstances. What it can do is stall less. What it actually does is add per instruction overhead (rename, allocate, queue, select, retire) on every instruction while removing only some stalls. Worse, every taken branch flushes a deeper window with no predictor to soften it, so the branch penalty grows exactly where CoreMark is most sensitive. Out of order execution only removes stalls; here it added more cycles than it removed, with no ceiling gain to pay for them.
Adding the front end: rv32i-ooo-FE
The natural reply is that the comparison is unfair: the rv32i-pipe side never got its predictor. rv32i-ooo-FE answers that: the same core with the optimised frontend (hybrid predictor, BTB, RAS). Branch flushes fell about 80% in relative terms, which confirms the predictor works in this pipeline too.
| Variant | Cycles | CoreMark/MHz | Note |
|---|---|---|---|
rv32i-pipe | 38877313 | 2.5722 | baseline |
rv32i-ooo | 45639092 | 2.1911 | predict not taken |
rv32i-ooo-FE | 40233631 | 2.4855 | CPI 1.3617 |
rv32i-pipe-FE | 31540922 | 3.1705 | best in order pipe |
Absolute numbers at O3 i100:
rv32i-pipe       38877313 cycles   2.5722 CM
rv32i-ooo        45639092 cycles   2.1911 CM
rv32i-ooo-FE     40233631 cycles   2.4855 CM   (CPI 1.3617)
rv32i-pipe-FE    31540922 cycles   3.1705 CM
The predictor recovered most of the branch loss: 11.8% fewer cycles than the unprotected rv32i-ooo. But the absolute position barely moved past the starting line: still 3.5% more cycles than the plain unoptimised rv32i-pipe, and 27.6% more than rv32i-pipe-FE. The overhead accounting is now clear. Rename, allocate, queue, select, and retire logic touch every instruction whether or not any reordering happens. The load path is longer. Each remaining flush discards a deeper window. And the ceiling never moved: peak IPC is 1.0 on both sides. rv32i-ooo-FE on this workload is a cost without a ceiling gain. That lesson set up the third experiment: the only place out of order execution can pay is where extra width gives it something to fill.
OoO on the dual issue core: rv32i-super-ooo-FE
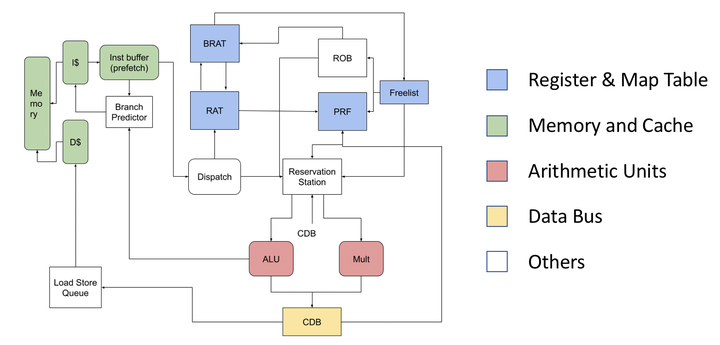
The third experiment skipped rv32i-superscalar entirely (an OOO on it was never built) and started from rv32i-super-FE: hybrid predictor, BTB, RAS, dual port LSU with 2 loads per cycle, full forwarding, and single cycle MUL/DIV/REM in EX. That base has a single cycle divider, which is unrealistic, and the comparison later keeps it in mind. The out of order core built on top, rv32i-super-ooo-FE, is 2 wide fetch, dispatch, issue, and retire, with a 32 entry ROB, a 16 entry issue queue split by FU class, dual ALUs, a dedicated MD pipe, a branch unit on pipe 0 only, dual CDBs, positional flush tags, and the hybp/BTB/RAS frontend kept as is. Loads and stores execute at retire in order, and dispatch allows only one branch in flight at a time. Those last two are limitations, and the numbers later say exactly what they cost.

The parts not shown in the picture: flush uses positional tags, and a rename map restore accompanies every redirect.
2 wide fetch + predict
  -> 2 wide dispatch + rename -> ROB 32
       -> ALU IQ -> ALU0, ALU1 ─┐
       -> MD IQ  -> MD         ─┼─ dual CDB -> ROB -> 2 wide retire
       -> BR IQ  -> BRU pipe 0 ─┘
       -> LSQ    -> LSU at retire (in order)
flush: positional tags, map restore at redirect
Performance comes after correctness, so the M extension tests ran first, before any CoreMark run: 7 small directed programs covering multiply, divide and remainder, division by zero, overflow and CSR behaviour. The MULH family came back with zero in rd. Reading alu.v showed the product computed in 32 bits and the upper half taken through a 32 bit shift, which is zero by construction. The products had to be widened to 64 bits, with the sign handling chosen per variant:
// alu.v: named, explicitly widened products, sign per MULH/MULHSU/MULHU.
wire signed [63:0] a_ss    = {{32{a[31]}}, a};
wire signed [63:0] prod_su = a_ss * {32'b0, b};
wire        [63:0] prod_uu = {32'b0, a} * {32'b0, b};
The divide and remainder edge test reported the wrong quotient for INT_MIN divided by -1. That case in the divide result mux used an unsigned -1 literal, which made the whole mux unsigned; a signed literal in its place corrected it. Division by zero returned 1 where the spec asks for all ones. The pipe core had run CoreMark clean with the same ALU, so all three faults went through the benchmark unseen, which says more about CoreMark’s coverage of the M extension than about the ALU. The directed tests exist because the benchmark cannot be trusted to hit corners.
Retire had a fault of its own, and the CSR directed test caught it: each retired CSR read came back one instruction late. The read was using the flopped CSR address, so by the time the retiring instruction sampled it the value belonged to the previous cycle. A second read port indexed by the retiring entry’s own CSR address corrected it:
// retire: read the entry that is retiring, not the cycle before it.
assign csr_rdata2 = csr_file[rob_csr[rob_head]];
The flush path produced state corruption right after taken branches. Comparing dumps at the first divergent retire showed a rename mapping that had survived the mispredict, so a map restore went in beside the flush. The flush kills every entry younger than the branch by positional tag, and the first version had no guard against an entry matching its own tag, which reading the tag distance logic made plain:
// kill younger entries on redirect, never the branch's own entry.
kill = flush_valid && (tag_dist(entry_tag, flush_tag) != 5'd0)
       && is_younger(entry_tag, flush_tag);
No change stayed in unless it passed all of these: the 7 directed M tests, the 31 test suite, binary search and fibonacci matching bit for bit, and all 9 CoreMark configs reaching HALT with exact state. Retired instruction counts are identical across every variant and config, which is the strongest single check that no wrong path instruction ever retired:
| Config | i1 | i10 | i100 |
|---|---|---|---|
| O2 | 322977 | 3102274 | 30899090 |
| O3 | 307171 | 2965056 | 29546307 |
| Ofast | 307169 | 2965054 | 29546305 |
retired instructions, every variant, Verilator:

config   i1        i10       i100
O2       322977    3102274   30899090
O3       307171    2965056   29546307
Ofast    307169    2965054   29546305
Two footnotes on that table, both found by state comparison rather than by failure. rv32i-super-FE once showed 307172 at i1 O3 against our 307171: a halt edge counting difference of one instruction, with identical memory. And it leaves x2 at 0x80001010 from a post ecall overrun in its halt path while ours stops at the initialised 0x80001800; every other register and all of memory match. Fibonacci retired 215 instructions after the later retiming work against 214 before, again with bit identical state: a halt edge shift, not a behavior change. The testbench had two quirks of its own. Back to back 12 cycle divides trip its 33 stable PC loop detector, which surfaced because the div tests failed only when the divides sat adjacent, so the directed tests space them out. And Icarus buffers its log when a run hangs, so hangs were diagnosed from binary freshness and state dumps.
First measurement of the correct rv32i-super-ooo-FE at i1 O3: 355184 cycles, CPI 1.1563, CoreMark/MHz 2.8154. Against rv32i-super-FE at 223472 cycles that is 1.59x in cycles, or 0.629x of that core. It was correct and slow, and the next section is about why.
Finding the stalls
Non functional stall breakdown counters were added to the RTL ([OOO] lines printed at halt, kept in the design afterwards). The first counter run showed retire slot 0 idle roughly 41% of cycles. An out of order core that cannot keep its own retire fed is either starved at dispatch or blocked at issue, and the counters split those cases per pipeline point. Two changes came out of the data, plus one attempt that was reverted.
Routing MUL to the ALU pipes. The [OOO] dump ranked MD busy far above every other stall counter at about 38K cycles. Counting multiplies in the disassembly gave 9491, and 9491 times 4.01 matches the counter almost exactly, which proved every multiply paid the full 4 cycle MD latency. Reading the dispatch steer showed why: every M extension op, including single cycle multiplies, was routed to the 4 cycle non pipelined MD pipe. The steer was changed to match DIV class only (funct3 bit 2 set), leaving MUL class as single cycle dual issue through the ALU pipes. The MD pipe kept a realistic 12 cycle divide; CoreMark executes 6 divides, so that latency is negligible here and realistic everywhere else.
// Dispatch steer: DIV class to MD, MUL class to the ALU pipes.
wire is_div_cls = (opcode == OP_M) && (funct3[2] == 1'b1);
wire disp_m = is_div_cls;   // was: (opcode == OP_M)
Saved about 31K cycles: 355184 to 324415, down 8.7%. CoreMark/MHz 2.8154 to 3.0825.
Resolving branches in the same cycle. After the MUL change the dump still showed two large branch counters: about 33K head execute waits and about 14K redirect stalls. Tracing a taken branch through the RTL showed the 3 cycle sequence behind them: latch in the dispatch section, resolve a cycle later, redirect a cycle after that. The fix latches the branch operands early, resolves inline with blocking regs, and lets the flush capture the redirect directly. One implementation detail mattered: combinational wires read stale values mid block in this style, so the inline resolve had to use regs (the first cut used wires and resolved stale values, which the state compare caught at once). After the change the branch wait counter reads 0, the redirect stall counter reads 0, and total flushes fell from 15193 to 14871.
taken branch, old timing:
  cycle N:    latch branch in dispatch
  cycle N+1:  resolve in BRU, redirect computed
  cycle N+2:  redirect takes effect        2 lost cycles per taken branch

taken branch, new timing:
  cycle N:    latch early, resolve inline, flush takes redirect
  cycle N+1:  fetch on the correct path   hx_bru 0, hb_red 0
// Early BRU resolve (simplified): latch early, resolve inline.
// Blocking regs, because comb wires read stale mid block here.
br_rs1 = rs1_val; br_rs2 = rs2_val;
br_taken = br_compare(br_rs1, br_rs2, funct3);
Saved about 36K cycles: 324415 to 288142, down 11.2%. Together with the MUL routing change: 355184 to 288142, down 18.9%. With both fixes in, the core becomes rv32i-super-oooo-FE; every number from here on is that core.
What was reverted: same cycle load retire. With branches fixed, the 1 cycle load completion bubble (lq_oth about 31K) looked like the next target. Same cycle load retire hung, and the state dump showed the signature: the ROB head never completed, stuck waiting on data that never arrived. Tracing the path showed the cross module combinational load data arrives stale mid block because of event ordering, so the fresh ROB entry never saw its own data. The change was reverted. That bubble is structural to this blocking assignment style; only earlier address generation issue shrinks it, not faster sampling at retire. It stays in the final numbers below.
A counter that turned out to be misread. A miss counter flagged thousands of cycles where a ready queue head sat unissued with its FU free (q_alu_f 5445, lq_f 2934). That pattern points at the select logic, so a trace was added that printed the full machine state on every miss. Every one of the 5445 ALU misses showed both lanes idle with ALUs free: the ROB was empty because dispatch had just refilled it, and select runs on the pre edge queue while the snapshot was taken post dispatch. Same cycle dispatch to issue is impossible in this style, so these are frontend bubbles misclassified as misses, not lost wakeups. The only remedy is keeping the ROB non empty, which points at the dispatch gate discussed in the gap section.
Post fix counters for rv32i-super-oooo-FE, table plus raw dump (i1 O3, Icarus; Verilator reads 288142, agreement to within 1 cycle):
| Counter | Cycles | Share | Reading |
|---|---|---|---|
| dispatches | 347994 | 113.3% of retired | incl. wrong path |
| flushes | 14871 | 4.3% of dispatches | was 15193 |
| dispatch held (bar) | 69781 | 24.2% | backpressure |
| branch gate (hb_br) | 66621 | 23.1% | one branch in flight |
| retire idle, load side (ldar) | 50259 | 17.4% | load path idle |
| load settle (lq_oth) | 30874 | 10.7% | 1 cycle completion bubble |
| retire idle, exec side (ex) | 23766 | 8.2% | execute path idle |
| load queue waits (lq_alu) | 16451 | 5.7% | operands not ready |
| issue waits (hx iqr) | 12067 | 4.2% | operands not ready |
| head ALU wait (hx_alu) | 11642 | 4.0% | operands not ready |
| ROB empty (empty) | 7988 | 2.8% | frontend bubbles |
| JALR issue wait (q_bru) | 6622 | 2.3% | gate looks removable |
| ready unissued, ALU (alu_f) | 5445 | 1.9% | misclassified bubbles |
| JALR dispatch gate (hb_jalr) | 3154 | 1.1% | blocks all dispatch |
| ready unissued, LQ (lq_f) | 2934 | 1.0% | misclassified bubbles |

The chart groups the long tail into “Other” and adds a “Useful work (retire)” bar for scale: even after both fixes, the machine spends more cycles held at the branch gate alone than it spends on anything else in the dump except retiring instructions.
[OOO] 288141 cycles, disp 347994, retired 307171, flushes 14871 (was 15193)
hold bar 69781
idle: empty 7988, ldar 50259, ex 23766
hx:   alu 11642, bru 0 (was ~33K), iqr 12067
lq:   alu 16451, iqr 2934, oth 30874
hb:   br 66621, red 0 (was ~14K), jalr 3154
split q: alu_f 5445, bru 6622, lq_f 2934, alu_b 0, md 0, lq_b 0
Small tests for rv32i-super-oooo-FE after the fixes: binary search runs 601 cycles against the 643 cycle rv32i-super-FE golden with 463 retired and exact state, down 6.5%, which is a genuine win on branch heavy tiny code. Fibonacci runs 285 cycles, down from 296. The 31 test suite halts in 62 cycles, down from 69, 31/31 PASS. The M suite stays 7/7. Verilator builds with 0 latches and no new warnings.
| Test | Cycles | Reference | State |
|---|---|---|---|
| Binary search | 601 | 643 in order golden, down 6.5% | exact, 463 retired |
| Fibonacci | 285 | was 296, down 3.7% | exact, 215 retired |
| 31 test suite | 62 | was 69, down 10.1% | 31/31 PASS |
| M extension suite | 7/7 PASS | mul divrem divu div0a div0b ovf csr | exact |
BS 601c/463r exact (golden 643c, down 6.5%)
FIB 285c/215r exact (was 296c, down 3.7%)
31t 62c 31/31 PASS (was 69c, down 10.1%)
M 7/7 PASS, Verilator 0 latches, no new warnings
| Stage | Cycles | CoreMark/MHz | CPI | vs in order base |
|---|---|---|---|---|
rv32i-super-ooo-FE start | 355184 | 2.8154 | 1.1563 | 0.629x |
| + MUL to ALU pipes | 324415 | 3.0825 | 1.0561 | 0.689x |
rv32i-super-oooo-FE final | 288142 | 3.4705 | 0.9381 | 0.776x |
CPI waterfall at i1 O3:

 1.1563  rv32i-super-ooo-FE (start)
-0.1002  MUL to ALU pipes
-0.1180  same cycle BRU resolve
 =======
 0.9381  rv32i-super-oooo-FE (final)
Final numbers
Verilator, all 9 configs of rv32i-super-oooo-FE to HALT, all exact state. Improvement over the rv32i-super-ooo-FE start is uniform: 18.6% to 19.3% fewer cycles in every config.
| Config | Cycles | CoreMark/MHz | Base CoreMark/MHz | Ratio |
|---|---|---|---|---|
| i1_o2 | 304182 | 3.2875 | 4.2440 | 0.775x |
| i10_o2 | 2938906 | 3.4026 | 4.4102 | 0.772x |
| i100_o2 | 29314448 | 3.4113 | 4.4269 | 0.771x |
| i1_o3 | 288142 | 3.4705 | 4.4748 | 0.776x |
| i10_o3 | 2796479 | 3.5759 | 4.6377 | 0.771x |
| i100_o3 | 27891100 | 3.5854 | 4.6545 | 0.770x |
| i1_ofast | 285153 | 3.5069 | 4.4737 | 0.784x |
| i10_ofast | 2775834 | 3.6025 | 4.6372 | 0.777x |
| i100_ofast | 27678505 | 3.6129 | 4.6535 | 0.776x |
config      OOOO cycles  OOOO CM  base CM   ratio
i1_o2       304182       3.2875   4.2440    0.775x
i10_o2      2938906      3.4026   4.4102    0.772x
i100_o2     29314448     3.4113   4.4269    0.771x
i1_o3       288142       3.4705   4.4748    0.776x
i10_o3      2796479      3.5759   4.6377    0.771x
i100_o3     27891100     3.5854   4.6545    0.770x
i1_ofast    285153       3.5069   4.4737    0.784x
i10_ofast   2775834      3.6025   4.6372    0.777x
i100_ofast  27678505     3.6129   4.6535    0.776x
Where the final core sits at i100 O3, best first:
| Rank | Variant | CoreMark/MHz (i100 O3) |
|---|---|---|
| 1 | rv32i-super-FE | 4.6545 |
| 2 | rv32i-super-oooo-FE | 3.5854 |
| 3 | rv32i-pipe-FE | 3.1705 |
| 4 | rv32i-pipe | 2.5722 |
| 5 | rv32i-ooo-FE | 2.4855 |
| 6 | rv32i-ooo | 2.1911 |

Two comparisons matter. Against rv32i-pipe-FE, rv32i-super-oooo-FE leads by 13.1% (3.5854 vs 3.1705): width plus reordering beats a tuned single issue core. Against rv32i-super-FE, it trails by 1.29x in cycles (288142 vs 223472 at i1 O3). The fixes recovered a fifth of the core’s own cycles and none of that changes the second comparison enough. The next section explains the gap with counter shares.
Why rv32i-super-oooo-FE still trails its in order base
The result looks backwards if you only think of OoO as “finding work that would otherwise be stalled.” The important question is what is actually preventing this particular OoO machine from finding that work.
Four items show up in the counters, ordered by measured size.
1. The single branch dispatch gate. Dispatch allows one branch in flight at a time, and the hold counter for that gate reads 66621 cycles: 23.1% of the run, the largest single counter in the dump. While a branch is in flight, dispatch stops, the ROB drains, address generation completes at the queue head with nothing behind it, and the machine pays the ROB empty bubbles the trace exonerated earlier. This is the binding constraint. Removing it means multiple branches in flight with branch unit squash on redirect, and the risk is real: out of order GHR updates can hurt prediction on history sensitive kernels. It was not attempted.
2. The in order LSU. Memory ops execute at retire, one load per cycle, against a base that sustains 2 loads per cycle from a dual port LSU with forwarding. Add the 1 cycle settle bubble the reverted fix failed to remove (lq_oth 30874, or 10.7% of cycles) and the load path is slower in every dimension: issue rate, latency tolerance, and forwarding. An out of order load path with a second port is the largest structural change remaining.
3. The JALR gates. JALR blocks all dispatch while in flight (hb_jalr 3154, 1.1%), and JALR issue waits for no branch in flight (q_bru 6622, 2.3%). The counters put 6.6K cycles behind the issue gate and 3.2K behind the dispatch gate, and the issue gate looks removable: JALR skips the GHR and BTB updates are order insensitive, so waiting gains nothing. That is the cheapest identified win, around 2%, and it was left in place as the stopping point.
4. The divider. The 12 cycle divide was kept deliberately against the base’s single cycle divider. Six divides in CoreMark make this worth almost nothing here, but the comparison flatters the base on any divide heavy code and the numbers above should be read with that in mind.
Net: rv32i-super-oooo-FE wins where the workload has branch heavy bursts its window can absorb (binary search beats rv32i-super-FE by 6.5%) and loses where rv32i-super-FE already removed the same stalls at lower cost (CoreMark, by 1.29x). That core sits at 89.5% of its available headroom from the previous post’s accounting; there was little left to find, and the finding cost more than it returned.
Reproduce it: commands and raw output
Toolchain: Verilator 5.032, Icarus 12.0, riscv64 linux gnu toolchain with riscv32 objdump and objcopy symlinks. CoreMark figures are Verilator only throughout; Icarus was used for fast iteration and agrees to within 1 cycle.
sudo apt-get install -y iverilog verilator gcc-riscv64-linux-gnu

iverilog -g2005 -f tb/tb_program.f -o /tmp/supoo.vvp
make verilator-prog

python3 scripts/elf2hex.py coremark_i100_o3.elf hex/inst_mem.hex hex/data_mem.hex
./obj_dir/Vtb_program

cat tb_program_results.txt
cp tb_program_results.txt tb_program_results_i100_o3.txt
The results parser, same shape as the previous post:
import re

def parse(path):
    txt = open(path).read()
    cycles = int(re.search(r"Total cycles:\s*(\d+)", txt).group(1))
    inst = int(re.search(r"Retired instructions:\s*(\d+)", txt).group(1))
    return cycles, inst

runs = [
    ("O3", 1, "tb_program_results_i1_o3.txt"),
    ("O3", 10, "tb_program_results_i10_o3.txt"),
    ("O3", 100, "tb_program_results_i100_o3.txt"),
]

for opt, iters, path in runs:
    cycles, inst = parse(path)
    cpi = cycles / inst
    ipc = inst / cycles
    cm_mhz = (iters * 1_000_000) / cycles
    print(f"{opt} ITER={iters}: cycles={cycles}, inst={inst}, "
          f"CPI={cpi:.9f}, IPC={ipc:.9f}, CoreMark/MHz={cm_mhz:.9f}")
Raw output for rv32i-super-oooo-FE:
O3 ITER=1: cycles=288142, inst=307171, CPI=0.938050793, IPC=1.066040355, CoreMark/MHz=3.470511067
O3 ITER=10: cycles=2796479, inst=2965056, CPI=0.943145425, IPC=1.060281876, CoreMark/MHz=3.575925297
O3 ITER=100: cycles=27891100, inst=29546307, CPI=0.943979226, IPC=1.059345347, CoreMark/MHz=3.585373112
Directed M extension tests build with the bare metal flow (as, then ld with the link at 0 script, because gcc -Ttext fails on this target):
riscv64-linux-gnu-as -march=rv32im_zicsr_zifencei -mabi=ilp32 -o mtests/div0a.o mtests/div0a.s
riscv64-linux-gnu-ld -m elf32lriscv -T test_hex/link_at_0.ld -o mtests/div0a.elf mtests/div0a.o
python3 scripts/elf2hex.py mtests/div0a.elf hex/inst_mem.hex hex/data_mem.hex
./obj_dir/Vtb_program
mul PASS, divrem PASS, divu PASS, div0a PASS, div0b PASS, ovf PASS, csr PASS
7/7 PASS, 31 test suite 31/31 PASS, CoreMark 9/9 HALT exact state
What this does not cover
The measurements use the included fixed-latency memory and do not establish behaviour with variable memory latency. Timing closure, Fmax, area and power need synthesis, which this post does not attempt; forwarding muxes, register-file ports, tag comparators and broadcast buses have physical timing and area consequences that simulation does not expose.
MILESTONE [Revisiting the OoO scheduling limits]
The earlier counters and traces pointed to restrictions before execution, not a shortage of arithmetic units. Instructions that could have been independent were sometimes held outside the scheduling window, while loads with ready addresses waited for retirement. I addressed these constraints in both the scalar and dual-issue OoO cores, preserving each core’s issue width and existing window sizes.
This pass uses the checked-in scalar rv32i-ooo-FE and dual-issue rv32i-super-ooo-FE versions, rather than the separate same-cycle branch-resolution checkpoint named rv32i-super-oooo-FE above. Each baseline was rebuilt from revision 5bce45d, and its shipped CoreMark ELF was kept unchanged for the paired before-and-after runs. The scalar core has one issue and retirement slot, a 16-entry ROB and an 8-entry issue queue. The dual-issue core has two slots, a 32-entry ROB, a 16-entry issue queue, two CDBs and two memory ports. Both use the included fixed-latency memory model.
Following the waits through the machine
I compared dispatch eligibility, operand readiness, execution-unit availability, result broadcast and retirement against the committed instruction trace. That made it possible to distinguish a true data dependency from a delay imposed by a control or memory policy. A second conditional branch could not enter while the first remained unresolved, and an unresolved JALR could hold back the stream more broadly. Independent instructions left outside the issue queue were beyond the reach of the oldest-ready selector. The revised control window admits up to four unresolved conditional branches or JALRs and selects the next control behind the one currently resolving. Correctly predicted branches no longer impose an extra dispatch-cycle wait before another control can enter.
A wider control window also requires redirects to cancel younger work consistently. A redirect now cancels younger queue entries and pending load responses. An instruction selected before the edge is checked against its live ROB tag and sequence before issue; surviving entries retain their order, and allocation resumes after the surviving branch. This preserves age comparisons across sequence-counter wrap without increasing the ROB or adding a physical register file.
The load path showed a separate restriction. Address generation could happen out of order, but a load with a ready address still waited until it reached the ROB head before requesting data. The revised path selects an eligible load earlier and records its ROB tag and sequence with the request. Returned data can update the ROB and wake dependent instructions while an older instruction is waiting. Register writes and stores still commit in program order. An older store with an unknown address blocks the load, as does a known older store to the same physical word. A known-disjoint store may be bypassed, including while it waits for data. This does not add store-to-load forwarding or permit reads from MMIO to move ahead.
Effective addresses are now written directly to ROB metadata rather than consuming a CDB intended for register results. That leaves the result buses for loaded values and arithmetic completions. In the dual-issue core, completed loads can use the second retirement slot; a retiring store still owns its memory port, and arbitration holds completions that cannot be accepted. The scalar core carries one pending load response, while the dual-issue core can use both ports and its existing CDBs.
The dual-issue trace also showed that the second instruction in a fetched pair was treated as not taken even when its branch target had been learned. Prediction now covers both slots, with prediction metadata carried forward if a pair advances one slot at a time. Predictor training follows control-resolution order, and the return-address stack remains updated at retirement. A JALR’s link value is known as PC+4 even when its target still depends on an operand, so that link can now wake younger consumers without allowing the control instruction to retire early.
Fast multiply routing is retained in both designs: multiply-class instructions use the integer ALU paths, while divide and remainder remain on the MD path. This reduces contention on the shared MD unit, although it is not unique to OoO. The scheduling changes matter because they let renamed instructions already available to these paths use them.
What the feature runs show
The feature runs separate the effects rather than presenting them as a cumulative sequence. The control-window and second-slot-prediction cases retain head-only loads, while the early-load case retains the old control gates. Every row uses the same O3, 100-iteration ELF and produces the same final architectural state.
| Dual-issue OoO configuration | Cycles |
|---|---|
| Checked-in baseline | 34,399,552 |
| Consistent execution and retirement timing, legacy performance limits retained | 30,856,205 |
| Fast multiply, head-only loads, old control gates and slot-1 not-taken | 29,021,118 |
| Fast multiply and early loads, old control gates and slot-1 not-taken | 28,708,153 |
| Fast multiply and four-control window, head-only loads and slot-1 not-taken | 24,008,325 |
| Fast multiply and both-slot prediction, head-only loads and old control gates | 26,887,659 |
| Combined changes, one new load per cycle | 19,856,055 |
| Combined changes, up to two new loads per cycle | 19,746,429 |
With fast multiply held constant, the control-window case reduces cycles from 29,021,118 to 24,008,325. Early loads alone recover less while the old control gates remain. In combination, dispatch can bring more work into the window and earlier load completion can make that work ready sooner. Allowing a second new load per cycle reduces cycles by a further 0.55% relative to the combined one-load case. In the revised O3 one-iteration run, two instructions retire in 61.67% of measured cycles. The ROB peaks at 29 of its unchanged 32 entries; a separate full-window test reaches all 32.
Updated results
The paired OoO measurements use actual retired instruction counts. The interval ends at halt, and final state is captured after registered writes settle. Both O3, 100-iteration OoO programs retire 29,546,306 instructions.
| OoO core | Configuration | Cycles | CPI | IPC | CoreMark/MHz |
|---|---|---|---|---|---|
| Scalar | Checked-in baseline | 40,233,629 | 1.361714 | 0.734368 | 2.485483 |
| Scalar | Revised | 32,589,866 | 1.103010 | 0.906610 | 3.068439 |
| Dual issue | Checked-in baseline | 34,399,552 | 1.164259 | 0.858915 | 2.907015 |
| Dual issue | Revised | 19,746,429 | 0.668321 | 1.496286 | 5.064207 |
The revised scalar run uses 19.00% fewer cycles than its checked-in baseline; the revised dual-issue run uses 42.60% fewer. Across the nine O2, O3 and Ofast runs at 1, 10 and 100 iterations, input-image hashes, retirement counts and final architectural state match their respective baselines. The scalar cycle reductions range from 18.78% to 19.91%, and the dual-issue reductions from 41.76% to 44.20%.
Validation
Instruction traces and state comparisons accompany the cycle measurements. The revised dual-issue core passes 124 programs in both Verilator and Icarus, including store aliases, overlapping stores, wrong-path memory operations, repeated predicted calls and full-ROB flushes. The simulators agree on cycles, retirement counts, committed PCs, all 32 registers, all 2,048 data words and the 16 CSR storage slots. The scalar pass has 121 corresponding programs. Both also pass the original 31 register checks, and 1,024 M-extension results agree with mathematical expectations, QEMU and Spike.
The instruction fixtures enter their test bodies through a documented startup adaptation; they do not test complete privileged execution. This pass retains the existing CSR model and does not establish MRET, interrupt or coherent self-modifying-code support. The O3 100-iteration dual-issue run also matches the functional reference, and compiling out the performance counters leaves the revised cycle counts unchanged.
Two paths from an optimized pipeline
There are two ways to extend a single-issue pipeline: add a second in-order issue slot, or keep one-wide issue and add out-of-order scheduling. The OoO result should be checked against both the plain single-issue pipeline and the fully optimized one, because those baselines tell different parts of the story.
| Design point | Measurement status | CPI | IPC | CoreMark/MHz |
|---|---|---|---|---|
| Plain in-order, single issue | Published | 1.315810 | 0.760 | 2.572194 |
| Optimized in-order, single issue | Published | 1.067508 | 0.937 | 3.170484 |
| Optimized in-order, dual issue | Published | 0.727143 | 1.375245 | 4.654543 |
| Revised OoO, single issue | Measured here | 1.103010 | 0.906610 | 3.068439 |
The revised scalar OoO core does beat the plain single-issue in-order baseline:
$$ \frac{3.068439}{2.572194}-1=0.1929, \qquad +19.29\%. $$It does not beat the fully optimized single-issue pipeline, however:
$$ \frac{3.068439}{3.170484}-1=-0.0322, \qquad -3.22\%. $$The earlier in-order optimization raised the pipeline’s score from 2.572194 to 3.170484 before it was compared with the revised scalar OoO core. That is why saying simply that “single-issue OoO wins” or “single-issue OoO loses” is incomplete: it wins against the plain pipeline, but is slightly behind the optimized pipeline in this benchmark comparison.
Widening the optimized in-order pipeline produces a larger increase:
$$ \frac{4.654543}{3.170484}-1=0.4681, \qquad +46.81\%. $$The intuition is to think of issue slots as places to do useful work. A single-issue core has one place each cycle. OoO scheduling can move an independent instruction into that place when an earlier instruction waits, but it cannot create a second place or raise the one-wide ceiling. On this benchmark, the revised scalar OoO improves substantially over the plain pipeline, but it does not quite repay its extra rename, selection and retirement work relative to the already optimized in-order core.
A superscalar core adds another place to execute. That lane is useful only when a second independent instruction is available; dependencies, control-flow waits and load delays can leave it idle. OoO scheduling complements the added width by looking past a waiting instruction and selecting ready work for either lane. In this update, the control-window and earlier-load changes also reduce restrictions that could keep such work from reaching the scheduler. The width supplies capacity, while OoO and the scheduling changes help use it. This matches the superscalar model of Karkhanis and Smith, where true dependences constrain ideal issue rate and the finite window and disruptive events constrain sustained rate (paper).
This explains why the scalar and superscalar OoO comparisons need not have the same outcome. At one-wide issue, OoO only has the original slot to keep productive. At two-wide issue, the extra lane creates another opportunity to execute independent work while one instruction waits. The revised control and load paths help expose that work, and the combined superscalar OoO result is 8.80% above the published in-order superscalar score, as shown in the summary below.
One variant-name distinction matters here. In the original post, the scalar rv32i-ooo-FE scored 2.4855 CoreMark/MHz, below the plain in-order rv32i-pipe at 2.5722 and the optimized rv32i-pipe-FE at 3.1705. The 3.5854 result that beat the optimized single-issue pipeline by 13.1% was rv32i-super-oooo-FE, a dual-issue OoO core, not a scalar OoO core. The revised scalar OoO result in this update is 3.068439: it now beats the plain in-order baseline, but remains just below the optimized single-issue result. The values from the earlier post are published references, not reruns with the OoO binaries.
Summary
Combining the second issue slot with the revised OoO scheduling and load paths produces the strongest result in this comparison. The optimized in-order superscalar value is published; the superscalar OoO result is measured here.
| Dual-issue design | CPI | IPC | CoreMark/MHz |
|---|---|---|---|
| In-order superscalar, published | 0.727143 | 1.375245 | 4.654543 |
| Superscalar OoO, revised measurement | 0.668321 | 1.496286 | 5.064207 |
For a two-wide design, ideal throughput is two instructions per cycle, corresponding to a CPI floor of one half:
$$ \mathrm{IPC}_{\max}=2, \qquad \mathrm{CPI}_{\min}=\frac{1}{2}=0.5. $$The published in-order superscalar uses $1.375245/2=68.8\%$ of this issue-rate ceiling; the revised superscalar OoO uses $1.496286/2=74.8\%$. The CPI above the ideal floor falls from $0.727143-0.5=0.227143$ to $0.668321-0.5=0.168321$, a reduction of about 25.9% in this aggregate gap. This is not a claim that the gap consists of independent stall components.
The OoO window supplies a further resource bound. Little’s law relates average in-flight work to throughput and average residence time. For ROB capacity $W$ and average entry lifetime $L$:
$$ \mathrm{IPC}\leq\frac{W}{L}. $$With a 32-entry ROB, sustaining 1.496286 IPC would require an average ROB-entry lifetime no greater than $32/1.496286\approx21.4$ cycles if ROB capacity were the active limit. This is a bound, not a measurement of actual lifetime; the measured peak occupancy of 29 entries does not establish that the ROB is the bottleneck. This Little’s-law bound is used in out-of-order processor analysis (Sharif and Lee, Journal of Instruction-Level Parallelism).
The feature runs give measured evidence about the gains. Holding fast multiply constant, admitting a four-control window reduces cycles from 29,021,118 to 24,008,325, or 17.3%. Early loads with the old control gates reduce cycles from 29,021,118 to 28,708,153, or 1.1%. Allowing a second load per cycle after the combined changes reduces the one-load result by a further 0.55%. These are separate ablations and their gains are not additive. Across the full paired run, the revised dual-issue OoO core completes the same O3, 100-iteration workload in 19,746,429 cycles instead of the checked-in OoO core’s 34,399,552:
$$ S_{\text{measured}}=\frac{34{,}399{,}552}{19{,}746{,}429}=1.742, \qquad 1-\frac{19{,}746{,}429}{34{,}399{,}552}=42.6\% \text{ fewer cycles}. $$This is the measured combined speedup. Amdahl’s law expresses speedup as $S=1/((1-p)+p/s)$ for a fraction $p$ accelerated by a factor $s$. The overlapping counter events and interacting changes do not support assigning independent values to $p$ and $s$, so the measured before-and-after ratio and separate ablations are the appropriate evidence here.
For the fixed 100-iteration workload, the normalized score is $100\times1{,}000{,}000/C$, where $C$ is the cycle count. Therefore:
$$ \mathrm{CoreMark/MHz} =\frac{100{,}000{,}000}{19{,}746{,}429} =5.064207. $$Relative to the published in-order superscalar result, this is:
$$ \frac{5.064207}{4.654543}=1.0880, \qquad (1.0880-1)\times100\%=8.80\%. $$The comparison shows the two effects separately and together: the revised scalar OoO core beats the plain in-order pipeline but remains slightly below the fully optimized single-issue pipeline, while issue width gives a larger gain. The combined superscalar OoO result then improves on the published in-order superscalar score. Once combined with dual issue and the measured scheduling and load-path changes, the superscalar OoO core reaches 1.496286 IPC and 5.064207 normalized CoreMark/MHz, 8.80% above the published in-order superscalar result. Caches and longer memory latency can give OoO execution more independent work and latency to overlap. This result is the measured outcome on the benchmark here; a frequency-normalized simulation score does not establish physical clock rate.